
人工智能平台
人工智能平台
下面我再详细介绍一下常见的人工智能平台:
1. TensorFlow:作为目前最受欢迎的深度学习框架之一,TensorFlow支持多种硬件和操作系统,包括GPU、TPU等,并提供了丰富的工具和API,能够快速构建和训练深度学习模型。
2. PyTorch:和TensorFlow类似,PyTorch也是一种灵活的深度学习框架,支持自动微分和动态图,可以快速构建原型并且易于调试,因此它非常适合在研究和开发阶段使用。
3. Keras:Keras是由用户体验、模块易于扩展、模型便于维护等特点,因此非常适合用于快速构建模型的原型,降低深度学习入门门槛,以及非专业开发人员。
4. Microsoft Azure:Microsoft Azure是一种基于云计算的人工智能平台,为用户提供了广泛的人工智能工具、服务、SDK等,包括自然语言理解、视觉识别、语音识别等方面的技术,能够满足不同类型的业务需求和应用场景。
5. IBM Watson:IBM Watson是一种智能化的人工智能平台,能够帮助用户快速构建自定义混合多云平台,支持人工智能技术和工具的整合和应用,被广泛应用于医疗、金融、能源等领域。
6. Amazon Web Services(简称AWS):AWS是Amazon 公司支持网页服务的云计算平台,其中包括多项人工智能服务、工具和SDK,包括视觉识别、语音识别、语音合成等技术,帮助极大地允许构建智能化的应用服务。
7. Alibaba Cloud(简称阿里云):阿里云是国内领先的云计算平台,其中包括多项人工智能服务和工具,支持自然语言处理、视觉智能等多个人工智能技术,灵活且易用,能够帮助用户构建高效、可靠的人工智能服务和应用。
综上所述,以上这些人工智能平台都可以帮助用户快速地构建高质量、高效率的人工智能模型和应用服务,并应用到不同的领域和业务需求中。
人工智能平台需求分析论文
人工智能平台需求分析论文随着信息技术的飞速发展,人工智能(AI)已经渗透到社会的各个领域,成为推动社会进步的重要力量。
人工智能平台作为实现AI技术应用的重要载体,其需求分析对于平台的设计、开发和优化至关重要。
本文将对人工智能平台的需求进行深入分析,以期为相关领域的研究和实践提供参考。
引言人工智能平台是集成了多种人工智能技术,提供统一接口和服务的软件系统。
它能够支持机器学习、自然语言处理、计算机视觉等多种AI 应用的开发和部署。
随着AI技术的不断进步和应用领域的不断拓展,对人工智能平台的需求也在不断增长。
因此,进行人工智能平台需求分析,明确平台的功能、性能、安全性等关键指标,对于构建高效、稳定、安全的人工智能平台具有重要意义。
人工智能平台需求分析的重要性在人工智能平台的开发过程中,需求分析是整个项目成功的关键。
一个准确、全面的需求分析可以确保平台设计满足用户的实际需求,避免资源浪费,并提高开发效率。
需求分析的重要性主要体现在以下几个方面:1. 确保功能满足用户需求:通过需求分析,可以明确用户对平台的期望功能,避免开发出与用户需求不符的产品。
2. 指导技术选型和架构设计:需求分析结果将直接影响技术选型和系统架构的设计,确保平台的技术实现能够满足需求。
3. 优化资源配置:准确的需求分析有助于合理分配开发资源,避免资源浪费。
4. 提高系统的可维护性和扩展性:良好的需求分析有助于构建易于维护和扩展的系统架构。
人工智能平台需求分析的主要内容人工智能平台的需求分析主要涉及以下几个方面:1. 功能性需求:包括平台需要支持的AI技术类型、数据处理能力、用户交互方式等。
2. 非功能性需求:涉及平台的性能、安全性、可靠性、可维护性等。
3. 用户需求:分析不同用户群体对平台的具体需求,如企业用户、开发者、普通用户等。
4. 市场和技术趋势:考虑当前市场对AI平台的需求以及技术发展趋势,预测未来可能的需求变化。
功能性需求分析功能性需求是平台需求分析的核心部分,它决定了平台的基本功能和操作方式。
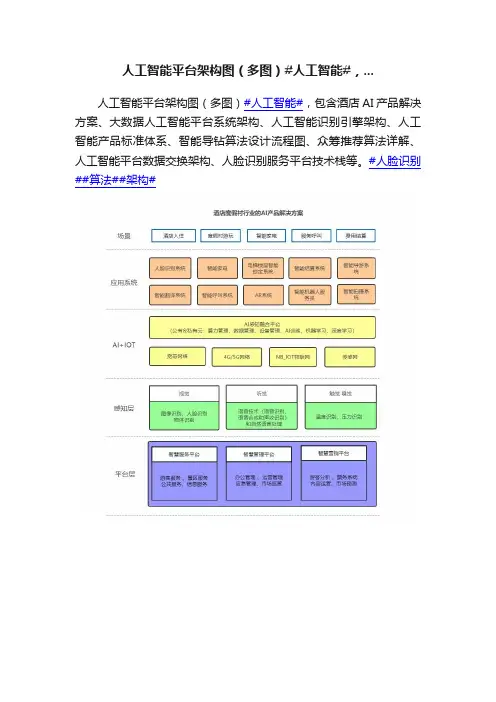
人工智能平台架构图(多图)#人工智能#,...
人工智能平台应用完整全套教学课件

系统、知识库系统到现在的机器学习、深度学习等高级阶段。
03
发展趋势
未来,人工智能平台将朝着更加智能化、开放化和可扩展化的方向发
展,同时将不断拓展应用领域,包括智能制造、智能家居、智慧金融
、智慧城市等。
02
人工智能平台的核心技术
机器学习
总结词
机器学习是人工智能平台的核心技术之一,通过分析大量数据并自动发现规律和 模式,从而进行预测和决策。
详细描述
在人工智能平台应用中,算法的准确性是 核心要素之一。为了提高算法的准确性, 需要对算法进行持续的优化和改进。这包 括但不限于改进模型结构、增加数据集、 调整参数等。通过不断优化算法,可以提 高平台应用的准确性和可靠性,从而更好 地满足用户需求。
升级硬件提升性能
总结词
通过升级硬件设备,提升人工智能平台的性能和响应速 度。
详细描述
计算机视觉是一种基于图像的技术,通过分析图像和视频等数据来实现视觉感知和图像处理。计算机 视觉技术包括目标检测、图像分类、图像分割等,可以应用于自动驾驶、智能安防、智能制造等领域 。
03
人工智能平台的应用场景
智能客服
总结词
智能客服是利用人工智能技术实现自动化 客户服务的新型机器人。它们能够自动应 答客户的咨询,解决常见问题,提高客户 满意度。
详细描述
人脸识别技术通过捕捉和提取人脸图像的特征信息,进 行比对和分析,实现身份识别和安全控制等功能。在金 融领域,人脸识别技术可用于远程开户、ATM机取款 等场景,提高金融安全和便捷性。在教育领域,人脸识 别技术可用于课堂点名、考试监考等场景,提高教育管 理的效率和准确性。此外,人脸识别技术还可用于安防 监控、门禁系统等场景,提高公共安全和社会管理效率 。
国家公布人工智能四大平台

、
1 9 m n I
储器 的 发 l l ,包 括 人 民
( 删
F i  ̄ T J‘
DI  ̄ . A M 内 顺 粒
公 牛 会 灰 永 .高 通 在 CDMA、 W C1 ) MA及 L TE 基 带 芯 ” 市 场
项¨ 1 预 算约 . 勺1 、 H ( 1 币 、合 f l F F 1 合 市 产 、 ’ 资
额 址公平 会创 以 来,对单一 公司 此案 经- - q : . ,公、 会 自公元
2 O 1 5 { i : - 2 月便 案对 通 眨开 调查 ,
控股 ( 集团 ) 仃限公司 ( 简 称 合 ) l O川 2 f 1 H签 署 了 《 J 俘 器研 发项 H
目 m ,美 固 尤 线 通 芯 片 商 高 通
递 公平 交 易法 ,m - . t } l , j 新 台币 2 3 4
城切 人 r 1 己 的力 , 破 除 外 断 ,
中 固 芯 " 计 t 兆 易 创新 1 1川
了 亡( 约 合 人民 币 j ( 1 J 亡) 的最 一 0 日 款。
C B l , l ~
, PC Bci t y CO r n cn
I n周查 的池 逋 收 同 内 外 的 : ‘ i ,
技I 合 J 1 : j 3 o ( ) 1 1 1 1 1 1 } ^ ( 1 2 、 _ r ) 、
造商 , I j 手机 I 和代 工 带 『 . 造 的
f 容 易 形成 断
二 、 湾 公
易 銮 会 1 0月 1 1
如 今 ,・ I
任 各 个 半 导
T 智能 开 敬 创 新 半 台 :3 、限 托 嘴 汛
AIStation 人工智能平台用户指南说明书
Artificial intelligence development platformRelease AI computing power, accelerate intelligent evolutionAI&HPCAIStation -Artificial Intelligence PlatformUser DataUtilizationTraining40%→80%2 days →4 hrs.Telecom FinanceMedicalManuf.Trans.Internet Development & TrainingDeployment & InferenceDeployment2 days →5 minDataModelServingLaptopMobileIndustryRobotIoTPyTorch Caffe MxNetPaddlePaddle TensorFlow ImportPre-processing accelerationTraining Visualization Hyper-para. tuningOn-demandAuto sched.OptimizationJupyter WebShell PipelineData mgnt computing resources Dev. ToolsModelTensorFlow ServingTensorRT Inference Server PyTorch Inference ServerServingDeployingDev. Tools PipelineData processing RecommendationsystemCV NLPScenarioOn-demand Auto sched.Optimization"Efficiency" has become a bottleneck restricting the development of enterprise AI businesspycharmjupyterVstudiosublime70%50%70%Data security issuesInefficient collaborative developmentLack of centralized data management Low resource utilizationInconvenient for large-scale trainingDecentralized Resource Management Lack of synergy in R&D, slow business responseR&D lacks a unified processAIStation –Artificial intelligence development platformTensorflow Pytorch Paddle Caffe MXNetAIStation Integrated development platformModel DevelopmentBuild environment Model Debugging Model OptimizationModel Deployment Model Loading Service DeploymentAPI ServiceModel Training Task Queuing Distributed Training Visual AnalysisAI computing resourcesTraining samplesApplication stackCPU GPUNFS BeeGFS HDFSComputing Resource Pooling User Quota management Utilizing GPU usagePool schedulingData accelerationAutomated DDP trainingSSDResource poolData pooldata1data2data3node1node2node3data4data5Dataset managementData pre-loading Cached data managementSolving data IO bottleneck Accelerating large scale dataset transferring and model trainingLow threshold for DDP training Helping developers drive massive computing power to iteratively trainmodelsbatch2batch1batch0Data loadingbatch3BeeGFSwork2GPU serverworker1GPUserverworker0GPUserverwork3GPU ServerAIStation TensorFlowCustomized MPI operatorsHighlighted featuresSSDSSDGPU GPU GPU GPU GPUGPUGPUGPUGPU Cards MIG instancesResource PoolingUser QuotaUser QuotaA I St a t i o n d e ve l o p m e n t P l a t f o r m A rc h i te c t u reP100V100V100sA100A30… …Ethernet ClusterInfiniband ClusterRoCE ClusterStorageNFS 、BeeGFS 、Lustre 、HDFS 、Object StorageLinux OSNVIDIA driver package: GPU, Mallanox NIC, etcOperating SystemHardware ClusterNVIDIAGPU seriesMonitoringSchedulingGPU PluginOperatorKubernetes + dockerNetwork PluginSRIOV PluginMultus CNIData prep.Algorithm prototype TrainingTestResource Enginedata mgmtJupyterimage mgmtwebshell/ssh multi-instance visualizationquota mgmtresource mgmt deployment job workflowmgmt job lifecycleproject mgmtalgorithm mgmtmodel mgmt Report HAMulti-tenant System settingBusiness ManagementAuthenticationAPIsAI Application Development3rd or user-defined system integrationDeployment ModeComputing Nodes Storage :SSD 2T-10TGPU :8*V100Management network Ethernet @ 1/10Gbps IPMIEthernet @ 1GbpsManagement Node Storage size :4T-100TCluster Size (10-80persons )ManagerDeployment Mode (Larger Scale+HA )Storage 100T-200TManagement network Ethernet @ 1/10Gbps IPMIEthernet @ 1Gbps Management Node 1*Main ,2*BackupCluster Size (10-80persons )Computing NodesSSD 2T-10T 8*V100Computing NodesSSD 2T-10T 8*V100Manager...I00G EDR infiniband EDR@100GpsOne-stop service full-cycle management,Easy use for distributed trainingHelping developers drive massive computing powerto iteratively train modelsOne-stop AI Dev. platformAI framework AI ops tools GPU driver & Cuda GPUStandard interface for AI Chips Multiply AI Chips supportedHeterogeneousComprehensive resource using statisticsData security and access control Automatic faulty analysis and solutionsIntelligent maintenance & securityHighlighted featuresAIStationStandard and unifiedManagementPollingSchedulingCPU GPU FPGAASICA100A30A40V100MLU270MLU390Cloud AIC 100•Personal data isolation•Collaborative sharing of public data •Unified data set managementC e n t r a l i z e d d a t a m a n a g e m e n tf a c i l i t a t e c o l l a b o r a t i v e d e v e l o p m e n t •Dataset preloading •Data Affinity Scheduling•Local cache management strategyD a t a c a c h e a c c e l e r a t i o ne f f e c t i v e l y s o l v e I /O b o t t l e n e c k s AIStation –Data Synergy Acceleration•Data access control•Data security sandbox, anti-download •Multiple copies ensure secure data backupS e c u r i t y p o l i c yUser DataTraining SamplesSharing Data(NFS 、HDFS 、BeeGFS 、Cloud Storage )D a t a M a n a g e m e n t :M u l t i -s t o r a g e Sy s t e m•Support “main -node ”storage using mode ;•Unified access and data usage for NFS 、BeeGFS 、HDFS 、Lustre through UI;•Built-in NFS storage supports small file merger and transfer, optimizing the cache efficiency of massive small filesAIStationComputing PoolStorage extension (storage interface 、data exchange )Data accelerationMain storageSSD+BeeGFSNode Storage(NFS )Node Storage(HDFS )Node Storage(Lustre )Data exchangeGPU PoolAIStationUser01UserNcaffeTensorflowmxnetpytorchGPUGPU GPU GPU GPUGPUGPUGPUGPU GPU GPU GPU GPUGPUGPUGPUGPU GPU GPU GPU GPUGPUGPUGPUGPU GPU GPU GPU GPUGPUGPUGPUAIStation –Resource SchedulingR e s o u r c e a l l o c a t i o n m a n a g e m e n tUser GPU resource quota limit User storage quota limitResource partition: target users, resource usageF l e x i b l e r e s o u r c e s c h e d u l i n g•Network topology affinity scheduling •PCIE affinity scheduling•Device type affinity scheduling •GPU fine-grained distributionD y n a m i c s c h e d u l i n g•Allocate computing resources on demand •Automatically released when task completedG P U M a n a g e m e n t :F i n e g r a n u l a r i t y G P U u s i n guser1user2user3user4user2481632123456GPU mem (G )Time (H )user1user2IdleIdle481632123456GPU mem (G )Time (H )GPU sharing scheduling policy based on CUDA to realize single-card GPU resource reuse and greatly improve computing resource utilization.Elastic sharing:Resources are allocated based on the number of tasks to be multiplexed.A single card supports a maximum of 64tasks to be multiplexed.Strict sharing:the GPU memory is isolated and allocated in any granularity (minimum:1GB).and resources are isolated based on thegraphics memory ;Flexible and convenient:user application to achieve "zero intrusion",easy application code migration ;S c h e d u l i n g w i t h M I G8 * A100 GPUsN V I D I A A100M I G s u p p o r t i n gUtilizing GPU usage• A single A100 GPU achieves up to 7x instance partitioning and up to56x performance on 8*A100 GPUs in Inspur NF5488A5;•Allocates appropriate computing power resources to tasks withdifferent load requirements.•Automatic MIG resource pool management, on-demand application,release after use;Convenient operation and maintenance•Set different sizes of pre-configured MIG instance templates.•Standard configuration UI for IT and DevOps team.•Simplify NVIDIA A100 utilization and resource management;56 *MIG instancesRe s o u rc e m a n a g e m e n t :N U M A ba s e d s c h e d u l i n gKubeletResource management PluginInspur-DevicePluginGPUGPU topo scoreGPU resource updateGPU allocatingAIStation SchedulerGPU allocationAutomatically detects the topology of compute nodes and preferentially allocates CPU and GPU resources in the same NUMA group to a container to make full use of the communication bandwidth in the groupAIStation –Integrated AI training frameworkPrivate image library PublicimagelibraryinspurAIimagelibraryAI DevelopmentFrameworkAI Developmentcomponents and toolsGPU Driver anddevelopment libraryGPU computingresources◆Te n s o r f l o w,P y t o r c h,P a d d l e,C a f f e,M X N e t◆B u i l d a p r i v a t e w a r e h o u s e t o m a n a g et h e A I a p p l i c a t i o n s t a c k◆S u p p o r t i m a g e c r e a t i o n a n d e x t e r n a li m p o r t◆S u p p o r t o p e n s o u r c e r e p o s i t o r i e s s u c ha s N G C a n d D o c k e r H u b◆B u i l t-i n m a i n s t r e a m d e v e l o p m e n t t o o l sa n d s u p p o r t d o c k i n g w i t h l o c a l I D E•Built-in Jupyter and Shell tools •Support docking with local IDE •Support command line operationQuickly enterdevelopment mode•Allocate computing resources on demand•Quick creation through the interface•Rapid Copy Development EnvironmentRapid build Model Development Environment•Life cycle management •Real-time monitoring of resource performance•One-click submission of training tasksCentralized management of development environmentQuickly build development environment, focus on model developmentD e ve l o p m e n t P l a t f o r mJupyterWebShell本地IDEDevelopment PlatformDev. Platform StatusDevelopment environment instancemonitoring The development environment saves the imageS e c o n d l e v e l b u i l d•On –demand GPU ;•T ensorflow/MXNet/Pytorch/Caffe ;•Single-GPU, multi-GPU, distributed training ;•Flexible adjustment of resources on demand decouples the binding of runtime environment and computing power ;I n t e r a c t i v e m o d e l i n g •Jupyter / WebShell / IDE V i s u a l i z a t i o nT ensorBoard / Visdom / NetscopeF u l l c y c l e m a n a g e m e n t S t a t u smonitoring/Performance monitoring/Port password memoryImage save/copy expansion/start/delete etcVisualizationTensorboardVisdom NetscopeEnhanced affinity scheduling, optimized distributed scheduling strategy, multi-GPU training acceleration ratio can reach more than 90%.Optimized most of the code based on open source;Fixed a bug where workers and launchers could not start at the same time;Task status is more detailed.•Supports distributed training for mainstream frameworks•Provides one-page submission and command line submission of training tasks.M u l t i p l e w a y s t o s u p p o r t d i s t r i b u t e dQ u i c k s t a r t d i s t r i b u t i o nI m p r o v e c o m p u t i n g p e r f o r m a n c eDistributed task scheduling to speed up model trainingAIStation –Training ManagementAIStation –Resource MonitoringO v e r a l l M o n i t o r i n g•Usage status of cluster resources such as GPU, CPU, and storage •Computing node health and performance•User task status and resource usageR e s o u r c e U s a g e St a t i s t i c s•Cluster-level resource usage statistics•Cluster-level task scale statistics•User-level resource usage statistics•User-level task scale statisticsS y s t e m A l a r m•hardware malfunction•System health status•Computing resource utilizationM u l t i -te n a n t M a n a g e m e n tAIStationUserUser2User group1User group2Kubernetes Namespace1Namespace2Cluster resource ☐Supports an administrator -Tenant administrator -Common User organization structure. Tenant administrators can conveniently manage user members and services in user groups, while platformadministrators can restrict access to and use of resources and data in user groups.☐User authentication: LDAP as user authentication system, supporting third-party LDAP/NIS systems.☐Resource quotas control for users and user groups using K8S namespace.☐User operations: Users can be added, logged out, removed, and reset passwords in batches. Users can be enabled or disabled to download data and schedule urgent tasks.I n t e l l i g e n t p l a t f o r m o p e r a t i o n a n d m a i n t e n a n c eIntelligent diagnosis and recovery tool•Based on the existing cluster monitoring, alarm and statistics functions, the operation monitoring component is removed to support independent deployment and use;•Health monitoring: Obtain the status and list display (monitoring information and abnormal events display) of components (micro-services and NFS).•Abnormal repair: Based on the operation and maintenance experience of AIStation, automatic or manual repair of the sorted events such as interface timeout and service abnormalities (microservice restart and NFS remount);Intelligent fault toleranceSupports active and standby management node health monitoring, HA status monitoring, and smooth switchover between active and standby management nodes without affecting services. Monitors alarms forabnormal computenode resource usage toensure the smoothrunning of computenodes.In the event of a systemfailure, the training taskautomatically startssmooth migrationwithin 30 secondsMonitor the status ofkey services andabnormal warning toensure the smoothoperation of user coreservices.M a n a g e m e n t n o d e h i g h l y a v a i l a b l e C o m p u t i n g n o d eF a u l t t o l e r a n c eC r i t i c a l s e r v i c e sf a u l t t o l e r a n tTr a i n i n g m i s s i o nf a u l t t o l e r a n c eN o r t h b o u n d i n t e r f a c e•Secure, flexible, extensible northbound interface based on REST APIs.AIStationQuery URL Status Usages Performance status logs performance resultsReturn URL resource framework scripts dataset environment Login info performance resource framework dataset Return URL Query URL Query URL Return URL monitordeveloping training Computing resourcesDatasets Applications Caffe TensorFlow Pytorch Keras MXNet theanodata1data2data3data4data5AIStation product featuresFull AI business process support Integrated cluster management Efficient computing resource scheduling Data caching strategy reliable security mechanismsUse Case :Automatic driveSolutions:•Increasing computing cluster resource utilization by 30% with efficient scheduler.•One-stop service full-cycle management,streamlined deployments.•Computing support, data management.Background :•Widely serving the commercial vehicle and passenger vehiclefront loading market. •The company provides ADAS and ADS system products andsolutions, as well as high-performance intelligent visualperception system products required for intelligent driving.U s e C a s e :c o m m u n i c a t i o n s te c h n o l o g y c o m pa n y•Quick deployment and distributed •GPU pooling •Huge files reading and training optimizationBackground•HD video conference and mobile conference are provided,and voice recognition and visual processing are the main scenarios.•Increased scale of sample data,distributed training deployment and management,a unified AI development platform is required to support the rapid development of service.ProblemsSolutions •Increasing size of dataset (~1.5T), distributed training;•GPU resource allocating automatically ;•Efficient and optimized management for the huge set of small files ;Use Case: Build One-Stop AI Workflow for Largest Excavator Manufacturer Revenue 15.7B$ExcavatorsPer Year 100,000+Factories 30+AIStation built one-stop AI workflow to connect cloud, edge,and localclusters; support 75 production systems.API Calls Per day 25 M QoS 0missper 10M calls Model Dev Cycle 2 weeks -> 3days Use AI to automate 90% production lines, double production capacity.SANY HEAVY INDUSTRY CO., LTDSANY CloudAIStationModel Dev &Training Inference ServiceSensor Data Data Download Realtime work condition analysis Inference API invoke Training Cluster Inference ClusterTraining Jobs InferenceServices200 * 5280M5 800 * T4, inference; 40* 5468M5 320 * V100, training。
人工智能系统平台验收报告

人工智能系统平台验收报告1. 引言本报告是对人工智能系统平台的验收工作进行总结和评估。
该平台旨在帮助用户进行各类人工智能任务的开发和管理,提供可靠和高效的解决方案。
2. 验收结果经过测试和评估,我们得出以下验收结果:- 系统功能完备:该人工智能系统平台提供了丰富的功能模块,能够满足用户的各类任务需求,包括数据预处理、模型训练、推理和性能评估等。
- 界面友好易用:平台的用户界面设计简洁直观,操作流程清晰易懂,即使对于非技术专业的用户也能够迅速上手。
- 高效稳定运行:在大规模任务的测试中,系统表现出优秀的性能,具有良好的稳定性和高并发处理能力,能够快速完成任务。
- 安全可靠保障:平台在数据隐私保护、系统安全和用户权限管理方面有良好的机制,能够确保用户数据和信息的安全。
3. 验收过程针对人工智能系统平台的验收,我们采取了以下步骤:- 制定验收方案:根据用户需求和系统设计,我们制定了详细的验收方案和测试用例。
- 进行功能测试:通过对系统各功能模块的测试,验证其功能是否符合要求。
- 进行性能测试:对系统进行了大规模的数据处理和推理性能测试,评估其运行效率和稳定性。
- 进行安全测试:针对系统的安全机制进行了测试和评估,确保用户数据和信息的安全性。
- 用户评估反馈:邀请用户参与测试,并收集用户的评估反馈,以进一步改进系统。
4. 验收结论通过对人工智能系统平台的全面测试和评估,我们得出以下结论:- 该平台功能完备,满足用户的各类任务需求。
- 用户界面友好易用,操作流程清晰简单。
- 平台具有高效稳定的运行性能,能够处理大规模任务。
- 平台拥有良好的安全可靠保障机制,保护用户的数据和信息安全。
5. 验收建议鉴于平台的良好表现,我们建议在进一步拓展以下方面:- 增加更多的模型和算法支持,提供更多样化的任务解决方案。
- 进一步优化平台的性能和稳定性,提高并发处理能力。
- 加强用户培训和技术支持,帮助用户更好地使用该平台。
人工智能平台建设技术方案
人工智能平台建设技术方案概述本文档旨在提供一个关于人工智能平台建设技术方案的详细概述。
该方案将侧重于利用现有技术和简单策略来构建一个功能完善且无法引发法律问题的人工智能平台。
目标我们的目标是建立一个高效、可靠且用户友好的人工智能平台。
该平台将为用户提供先进的人工智能功能,同时遵守法律和道德准则,保护用户的隐私和数据安全。
技术方案1. 基础设施为了构建一个稳定的人工智能平台,我们将采用以下基础设施:- 充足的计算资源:确保平台的性能和可扩展性,以满足用户的需求;- 可靠的存储系统:保证用户数据的安全存储和快速访问;- 强大的网络连接:确保平台能够快速传输数据和处理请求;- 高级的安全措施:采用加密和身份验证等措施,保护用户数据的机密性和完整性。
2. 数据管理在构建人工智能平台时,数据管理是关键之一。
以下是我们的数据管理策略:- 数据收集:确保从各种可靠来源收集大量的高质量数据,并符合适用的法律和隐私保护规定;- 数据清洗和预处理:使用现有的清洗和预处理技术,将原始数据转换为可用于训练和推理的格式;- 数据存储和索引:采用高效的存储和索引方法,以便快速访问和管理数据;- 数据安全与隐私保护:采取严格的安全措施,以确保用户数据的安全存储和传输,并遵守隐私保护法规。
3. 算法开发和优化优秀的算法是人工智能平台的核心,我们将采取以下措施:- 算法选择:选择适合特定任务的先进算法,并确保其合法性和适用性;- 算法开发:通过合理的实验设计和开发过程,设计和实现高效、准确的人工智能算法;- 算法优化:不断优化算法,以提升平台的性能和用户体验;- 算法测试:进行充分的测试和验证,确保算法的质量和可靠性。
结论本文档提供了一个人工智能平台建设技术方案的概述。
通过合理选择和运用现有的技术和策略,我们可以构建一个功能完善且无法引发法律问题的人工智能平台。
我们将致力于提供高质量的人工智能功能,同时遵守法律和道德准则,保护用户的隐私和数据安全。
人工智能平台有哪些
人工智能平台有哪些关键信息项:1、主流人工智能平台名称2、各平台的主要特点3、平台的应用领域4、平台的技术优势5、平台的使用成本6、平台的用户评价11 主流人工智能平台介绍111 TensorFlowTensorFlow 是一个广泛使用的开源深度学习框架,由Google 开发。
它具有高度的灵活性和可扩展性,支持多种编程语言,如 Python、C++等。
TensorFlow 拥有庞大的社区和丰富的资源,包括预训练模型和教程。
112 PyTorchPyTorch 是另一个流行的深度学习框架,以其动态计算图和易用性而受到开发者的喜爱。
它在研究领域和学术界应用广泛,并且与Python 的集成非常紧密。
12 各平台的主要特点121 灵活性不同的人工智能平台在灵活性方面有所差异。
一些平台允许用户自由定制模型结构和训练流程,而另一些则提供了较为固定的模板和框架。
122 性能优化部分平台在计算效率和内存使用方面进行了优化,能够在大规模数据和复杂模型上实现高效训练。
123 可视化支持一些人工智能平台提供了直观的可视化工具,帮助用户理解模型结构和训练过程中的数据流动。
13 平台的应用领域131 图像识别许多人工智能平台在图像识别任务中表现出色,如人脸识别、物体检测等。
132 自然语言处理包括文本分类、机器翻译、情感分析等领域,都可以借助人工智能平台实现高效的模型训练。
133 语音处理语音识别、语音合成等应用也能在合适的人工智能平台上得到支持。
14 平台的技术优势141 先进的算法一些平台采用了最新的深度学习算法和技术,提高了模型的准确性和泛化能力。
142 分布式训练支持对于大规模数据和计算需求,能够实现分布式训练,加快训练速度。
143 自动调参功能部分平台具备自动调整模型参数的能力,降低了用户的调参难度。
15 平台的使用成本151 免费开源平台一些人工智能平台是完全免费和开源的,用户可以自由使用和修改。
152 商业平台的收费模式部分商业平台可能按照使用时长、计算资源消耗等方式收费。
人工智能平台建设方案
人工智能平台建设方案
摘要
当今,人工智能技术发展迅速,大大提升了科学研究和社会服务的效率,但是,人工智能技术在我国还没有得到应有的发展,因此,建设多功能的人工智能平台显得尤为重要。
本文提出了建设多功能的人工智能平台的方案,该方案包括建立开放的人工智能系统、融合相关技术、强化数据和安全技术以及加强人工智能应用研究等步骤。
在实现全面提升人工智能技术研发的基础上,本文提出了具体技术实施路径,以帮助把建设多功能的人工智能平台付诸实施。
关键词:人工智能;平台建设;开放系统;融合技术
introduction
随着科学技术的发展,人工智能技术正在迅速发展,已经在许多行业应用有了不断的深入,从而大大提升了科学研究和社会服务的效率,为经济发展提供了强有力的技术支撑。
然而,由于各类资源的断续性、不完善和不充分,人工智能技术在我国还没有得到应有的发展,这就需要建立一个功能完善的人工智能平台来提供统一的、可重复利用的和不断改进的人工智能技术服务,从而支撑和推动社会与经济的可持续发展。
在此背景下,本文提出了建设多功能的人工智能平台的方案。
该方案包括:。
国家公布人工智能四大平台
国家公布人工智能四大平台
作者:
来源:《科学大观园》2018年第02期
事件:11月15日,中国新一代人工智能发展规划暨重大科技项目启动会在京召开,公布了第一批国家人工智能开放创新平台:依托百度建设自动驾驶国家新一代人工智能开放创新平台;依托阿里云建设城市大脑国家新一代人工智能开放创新平台;依托腾讯建设医疗影像国家新一代人工智能开放创新平台;依托科大讯飞建设智能语音国家新一代人工智能开放创新平台。
點评:这次会议的召开标志着新一代人工智能发展规划和重大科技项目进入全面启动实施阶段。
此次公布人工智能平台,是国家从7月发布《新一代人工智能发展规划》以来对人工智能产业发展的实质性推动举措,进一步明确了人工智能技术在产业升级中的颠覆性潜力。