
信息论习题集+答案(完版整)
信息论习题集 一、名词解释(每词2分)(25道) 1、“本体论”的信息(P3) 2、“认识论”信息(P3) 3、离散信源(11) 4、自信息量(12) 5、离散平稳无记忆信源(49) 6、马尔可夫信源(58) 7、信源冗余度 (66) 8、连续信源 (68) 9、信道容量 (95) 10、强对称信道 (99) 11、对称信道 (101-102)12、多符号离散信道(109) 13、连续信道 (124) 14、平均失真度 (136) 15、实验信道 (138) 16、率失真函数 (139) 17、信息价值率 (163) 18、游程序列 (181) 19、游程变换 (181) 20、L-D编码(184)、 21、冗余变换 (184) 22、BSC信道 (189) 23、码的最小距离 (193)24、线性分组码 (195) 25、循环码 (213) 二、填空(每空1分)(100道) 1、
在认识论层次上研究信息的时候,必须同时考虑到 形式、含义和效用 三个方面的因素。
2、 1948年,美国数学家 香农 发表了题为“通信的数学理论”的长篇论文,从而创立了信息论。 3、 按照信息的性质,可以把信息分成 语法信息、语义信息和语用信息 。 4、 按照信息的地位,可以把信息分成 客观信息和主观信息 。 5、 人们研究信息论的目的是为了 高效、可靠、安全 地交换和利用各种各样的信息。 6、
信息的 可度量性 是建立信息论的基础。
7、 统计度量 是信息度量最常用的方法。 8、 熵 是香农信息论最基本最重要的概念。 9、 事物的不确定度是用时间统计发生 概率的对数 来描述的。 10、单符号离散信源一般用随机变量描述,而多符号离散信源一般用 随机矢量 描述。 11、一个随机事件发生某一结果后所带来的信息量称为自信息量,定义为 其发生概率对数的负值 。 12、自信息量的单位一般有 比特、奈特和哈特 。 13、必然事件的自信息是 0 。 14、不可能事件的自信息量是 ∞ 。
15、两个相互独立的随机变量的联合自信息量等于 两个自信息量之和 。 16、数据处理定理:当消息经过多级处理后,随着处理器数目的增多,输入消息与输出消息之间的平均互信息量 趋于变小 。 17、离散平稳无记忆信源X的N次扩展信源的熵等于离散信源X的熵的 N倍 。
18、离散平稳有记忆信源的极限熵, 。 19、对于n元m阶马尔可夫信源,其状态空间共有 nm 个不同的状态。
20、一维连续随即变量X在[a,b]区间内均匀分布时,其信源熵为 log2(b-a) 。
21、平均功率为P的高斯分布的连续信源,其信源熵,Hc(X)=。
22、对于限峰值功率的N维连续信源,当概率密度 均匀分布 时连续信源熵具有最大值。 23、对于限平均功率的一维连续信源,当概率密度 高斯分布 时,信源熵有最大值。
24、对于均值为0,平均功率受限的连续信源,信源的冗余度决定于平均功率的限定值P和信源的熵功率 之比 。 25、若一离散无记忆信源的信源熵H(X)等于2.5,对信源进行等长的无失真二进制编码,则编码长度至少为 3 。
=∞H)/(lim121−∞→NNNXXXXHLePπ2log2
1
2
P
Page 1 of 9信息论题库
2010-1-11http://jpk.dqpi.net/xxl/mnxt.htmGenerated by Foxit PDF Creator © Foxit Softwarehttp://www.foxitsoftware.com For evaluation only.26、m元长度为ki,i=1,2,n的异前置码存在的充要条件是:。 27、若把掷骰子的结果作为一离散信源,则其信源熵为 log26 。 28、同时掷两个正常的骰子,各面呈现的概率都为1/6,则“3和5同时出现”这件事的自信息量是 log218(1+2 log23)。
29、若一维随即变量X的取值区间是[0,∞],其概率密度函数为,其中:,m是X的数学期望,则X的信源熵。 30、一副充分洗乱的扑克牌(52张),从中任意抽取1张,然后放回,若把这一过程看作离散无记忆信源,则其信源熵为 。
31、根据输入输出信号的特点,可将信道分成离散信道、连续信道、半离散或半连续 信道。 32、信道的输出仅与信道当前输入有关,而与过去输入无关的信道称为 无记忆 信道。 33、具有一一对应关系的无噪信道的信道容量C= log2n 。 34、强对称信道的信道容量C= log2n-Hni 。 35、对称信道的信道容量C= log2m-Hmi 。 36、对于离散无记忆信道和信源的N次扩展,其信道容量CN= NC 。
37、对于N个对立并联信道,其信道容量 CN = 。 38、多用户信道的信道容量用 多维空间的一个区域的界限 来表示。 39、多用户信道可以分成几种最基本的类型: 多址接入信道、广播信道 和相关信源信道。 40、广播信道是只有 一个输入端和多个输出端 的信道。
41、当信道的噪声对输入的干扰作用表现为噪声和输入的线性叠加时,此信道称为 加性连续信道 。
42、高斯加性信道的信道容量C=。 43、信道编码定理是一个理想编码的存在性定理,即:信道无失真传递信息的条件是 信息率小于信道容量 。
44、信道矩阵代表的信道的信道容量C= 1 。
45、信道矩阵代表的信道的信道容量C= 1 。 46、高斯加性噪声信道中,信道带宽3kHz,信噪比为7,则该信道的最大信息传输速率Ct= 9 kHz 。 47、对于具有归并性能的无燥信道,达到信道容量的条件是 p(yj)=1/m) 。
48、信道矩阵代表的信道,若每分钟可以传递6*105个符号,则该信道的最大信息传输速率Ct=10kHz 。
∑=−≤nikim11
mxemxp−=1)(0≥x
=)(XHCme2log
52log2
∑=NkkC1
)1(log212NXPP+
10002/12/1
100101
1001
Page 2 of 9信息论题库2010-1-11http://jpk.dqpi.net/xxl/mnxt.htmGenerated by Foxit PDF Creator © Foxit Softwarehttp://www.foxitsoftware.com For evaluation only.49、信息率失真理论是量化、数模转换、频带压缩和 数据压缩 的理论基础。 50、求解率失真函数的问题,即:在给定失真度的情况下,求信息率的 极小值 。 51、信源的消息通过信道传输后的误差或失真越大,信宿收到消息后对信源存在的不确定性就 越大 ,获
得的信息量就越小。 52、信源的消息通过信道传输后的误差或失真越大道传输消息所需的信息率 也越小 。 53、单符号的失真度或失真函数d(xi,yj)表示信源发出一个符号xi,信宿再现yj所引起的 误差或失真
。
54、汉明失真函数 d(xi,yj)= 。 55、平方误差失真函数d(xi,yj)=(yj- xi)2。
56、平均失真度定义为失真函数的数学期望,即d(xi,yj)在X和Y的 联合概率空间P(XY)中 的统计平均值。 57、如果信源和失真度一定,则平均失真度是 信道统计特性 的函数。
58、如果规定平均失真度不能超过某一限定的值D,即:。我们把称为 保真度准则 。
59、离散无记忆N次扩展信源通过离散无记忆N次扩展信道的平均失真度是单符号信源通过单符号信道的平均失真度的 N 倍。
60、试验信道的集合用PD来表示,则PD= 。 61、信息率失真函数,简称为率失真函数,即:试验信道中的平均互信息量的 最小值 。
62、平均失真度的下限取0的条件是失真矩阵的 每一行至少有一个零元素 。 63、平均失真度的上限Dmax取{Dj:j=1,2,,m}中的 最小值 。
64、率失真函数对允许的平均失真度是 单调递减和连续的 。 65、对于离散无记忆信源的率失真函数的最大值是 log2n 。 66、当失真度大于平均失真度的上限时Dmax时,率失真函数R(D)= 0 。
67、连续信源X的率失真函数R(D)= 。 68、当时,高斯信源在均方差失真度下的信息率失真函数为 。 69、保真度准则下的信源编码定理的条件是 信源的信息率R大于率失真函数R(D) 。
70、某二元信源其失真矩阵D=,则该信源的Dmax= a/2 。
71、某二元信源其失真矩阵D=,则该信源的Dmin= 0 。
72、某二元信源其失真矩阵D=,则该信源的R(D)= 1-H(D/a) 。 73、按照不同的编码目的,编码可以分为三类:分别是 信源编码、信道编码和安全编码 。 74、信源编码的目的是: 提高通信的有效性 。 75、一般情况下,信源编码可以分为 离散信源编码、连续信源编码和相关信源编码 。
≠=jiji10
DDD≤DD≤{}mjniDDxypij,,2,1,,,2,1;:)/(LL==≤
);()/(YXIPxypInfD∈
2σ≤D
=)(DR
D22log2
1σ
=2/12/110)(XPX00aa
=2/12/110)(XPX00aa
=2/12/110)(XPX00aa
Page 3 of 9信息论题库2010-1-11http://jpk.dqpi.net/xxl/mnxt.htmGenerated by Foxit PDF Creator © Foxit Softwarehttp://www.foxitsoftware.com For evaluation only.
信息论考试题及答案
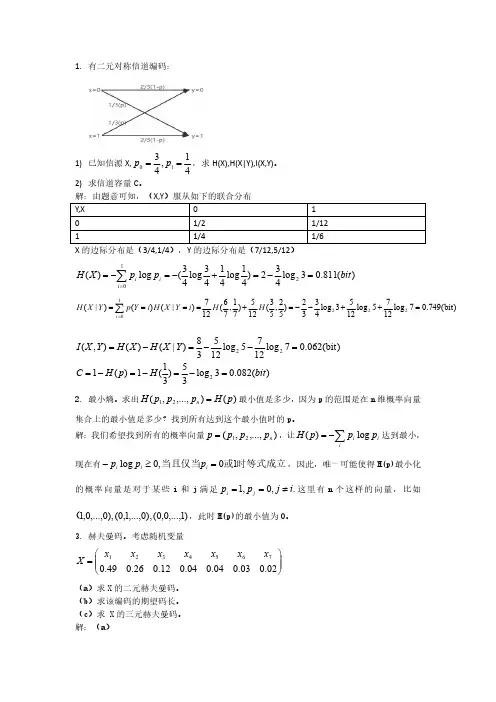
1.有二元对称信道编码:1)已知信源X,41,4310==p p ,求H(X),H(X|Y),I(X,Y)。
2)求信道容量C 。
解:由题意可知,(X,Y )服从如下的联合分布Y,X0101/21/1211/41/6X 的边际分布是(3/4,1/4),Y 的边际分布是(7/12,5/12))(811.03log 432)41log 4143log 43(log )(210bit p p X H i i i =-=+-=-=∑=)bit (749.07log 1275log 1253log 433252,53(125)71,76(127)|()()|(22210=++--=+====∑=H H i Y X H i Y p Y X H i )bit (062.07log 1275log 12538)|()(),(22=--=-=Y X H X H Y X I )(082.03log 35)31(1)(12bit H p H C =-=-=-=2.最小熵。
求出)(),...,,(21p H p p p H n =最小值是多少,因为p 的范围是在n 维概率向量集合上的最小值是多少?找到所有达到这个最小值时的p。
解:我们希望找到所有的概率向量),...,,(21n p p p p =,让∑-=i ii p p p H log )(达到最小,现在有时等式成立或当且仅当10,0log =≥-i i i p p p ,因此,唯一可能使得H(p)最小化的概率向量是对于某些i 和j 满足.,0,1i j p p j i ≠==这里有n 个这样的向量,比如)1,...,0,0(),0,...,1,0(),0,...,0,1(,此时H(p)的最小值为0。
3.赫夫曼码。
考虑随机变量⎪⎪⎭⎫ ⎝⎛=02.003.004.004.012.026.049.07654321x x x x x x x X (a)求X 的二元赫夫曼码。
姜丹 信息论与编码习题参考答案
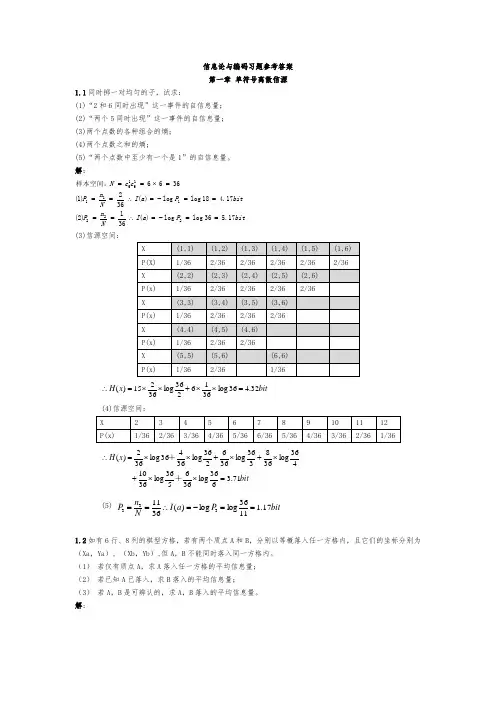
信息论与编码习题参考答案 第一章 单符号离散信源1.1同时掷一对均匀的子,试求:(1)“2和6同时出现”这一事件的自信息量; (2)“两个5同时出现”这一事件的自信息量; (3)两个点数的各种组合的熵; (4)两个点数之和的熵;(5)“两个点数中至少有一个是1”的自信息量。
解:bitP a I N n P bitP a I N n P c c N 17.536log log )(361)2(17.418log log )(362)1(3666样本空间:2221111616==-=∴====-=∴===⨯==(3)信源空间:bit x H 32.436log 3616236log 36215)(=⨯⨯+⨯⨯=∴ (4)信源空间: bitx H 71.3636log 366536log 3610 436log 368336log 366236log 36436log 362)(=⨯⨯+⨯+⨯+⨯⨯=∴++ (5) bit P a I N n P 17.11136log log )(3611333==-=∴==1.2如有6行、8列的棋型方格,若有两个质点A 和B ,分别以等概落入任一方格内,且它们的坐标分别为(Xa ,Ya ), (Xb ,Yb ),但A ,B 不能同时落入同一方格内。
(1) 若仅有质点A ,求A 落入任一方格的平均信息量; (2) 若已知A 已落入,求B 落入的平均信息量; (3) 若A ,B 是可辨认的,求A ,B 落入的平均信息量。
解:bita P a P a a P a I a P A i 58.548log )(log )()(H 48log )(log )(481)(:)1(481i i i i i ==-=∴=-=∴=∑=落入任一格的概率 bitb P b P b b P b I b P A i 55.547log )(log )()(H 47log )(log )(471)(:B ,)2(481i i i i i ==-=∴=-=∴=∑=落入任一格的概率是落入任一格的情况下在已知 bitAB P AB P AB H AB P AB I AB P AB i i i i i i i 14.11)4748log()(log )()()(log )(471481)()3(47481=⨯=-=-=∴⨯=∑⨯=是同时落入某两格的概率1.3从大量统计资料知道,男性中红绿色盲的发病率为7%,女性发病率为0.5%.如果你问一位男士:“你是否是红绿色盲?”他的回答可能是:“是”,也可能“不是”。
信息论第二章答案
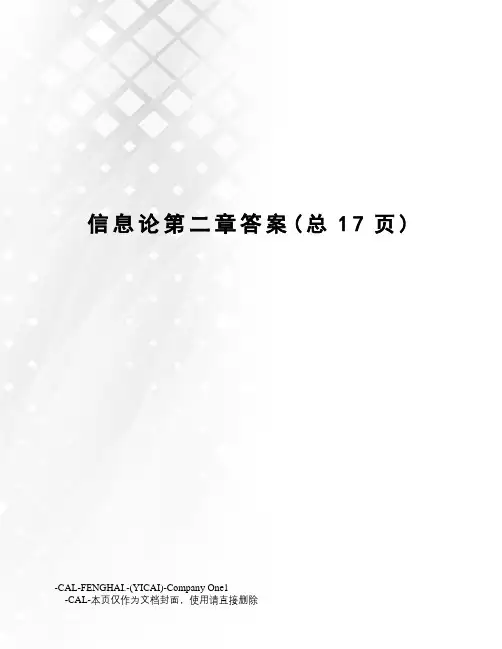
信息论第二章答案(总17页) -CAL-FENGHAI.-(YICAI)-Company One1-CAL-本页仅作为文档封面,使用请直接删除试问四进制、八进制脉冲所含信息量是二进制脉冲的多少倍解:四进制脉冲可以表示4个不同的消息,例如:{0, 1, 2, 3}八进制脉冲可以表示8个不同的消息,例如:{0, 1, 2, 3, 4, 5, 6, 7}二进制脉冲可以表示2个不同的消息,例如:{0, 1}假设每个消息的发出都是等概率的,则:四进制脉冲的平均信息量symbol bit n X H / 24log log )(1===八进制脉冲的平均信息量symbol bit n X H / 38log log )(2===二进制脉冲的平均信息量symbol bit n X H / 12log log )(0===所以:四进制、八进制脉冲所含信息量分别是二进制脉冲信息量的2倍和3倍。
一副充分洗乱了的牌(含52张牌),试问(1) 任一特定排列所给出的信息量是多少(2) 若从中抽取13张牌,所给出的点数都不相同能得到多少信息量解:(1) 52张牌共有52!种排列方式,假设每种排列方式出现是等概率的则所给出的信息量是: !521)(=i x p bit x p x I i i 581.225!52log )(log )(==-=(2) 52张牌共有4种花色、13种点数,抽取13张点数不同的牌的概率如下:(a)p(x i )=52/52 * 48/51 * 44/50 * 40/49 * 36/48 * 32/47 * 28/46 * 24/45 * 20/44 * 16/43 * 12/42 * 8/41 * 4/40=(b)总样本:C 1352, 其中13点数不同的数量为4*4*4*…*4=413。
所以,抽取13张点数不同的牌的概率:bit C x p x I C x p i i i 208.134log )(log )(4)(135213135213=-=-==居住某地区的女孩子有25%是大学生,在女大学生中有75%是身高160厘米以上的,而女孩子中身高160厘米以上的占总数的一半。
信息论和编码理论第二章习题集答案解析(王育民)

部分答案,仅供参考。
2.1信息速率是指平均每秒传输的信息量点和划出现的信息量分别为3log ,23log ,一秒钟点和划出现的次数平均为415314.0322.01=⨯+⨯一秒钟点和划分别出现的次数平均为45.410那么根据两者出现的次数,可以计算一秒钟其信息量平均为253log 4153log 4523log 410-=+2.3 解:(a)骰子A 和B ,掷出7点有以下6种可能:A=1,B=6; A=2,B=5; A=3,B=4; A=4,B=3; A=5,B=2; A=6,B=1 概率为6/36=1/6,所以信息量-log(1/6)=1+log3≈2.58 bit(b) 骰子A 和B ,掷出12点只有1种可能: A=6,B=6概率为1/36,所以信息量-log(1/36)=2+log9≈5.17 bit 2.5解:出现各点数的概率和信息量:1点:1/21,log21≈4.39 bit ; 2点:2/21,log21-1≈3.39 bit ; 3点:1/7,log7≈2.81bit ; 4点:4/21,log21-2≈2.39bit ; 5点:5/21,log (21/5)≈2.07bit ; 6点:2/7,log(7/2)≈1.81bit平均信息量:(1/21)×4.39+(2/21)×3.39+(1/7)×2.81+(4/21)×2.39+(5/21)×2.07+(2/7)×1.81≈2.4bit 2.7解:X=1:考生被录取; X=0:考生未被录取; Y=1:考生来自本市;Y=0:考生来自外地; Z=1: 考生学过英语;Z=0:考生未学过英语P(X=1)=1/4, P(X=0)=3/4; P(Y=1/ X=1)=1/2; P(Y=1/ X=0)=1/10; P(Z=1/ Y=1)=1, P(Z=1 / X=0, Y=0)=0.4, P(Z=1/ X=1, Y=0)=0.4, P(Z=1/Y=0)=0.4 (a) P(X=0,Y=1)=P(Y=1/X=0)P(X=0)=0.075, P(X=1,Y=1)= P(Y=1/X=1)P(X=1)=0.125P(Y=1)= P(X=0,Y=1)+ P(X=1,Y=1)=0.2P(X=0/Y=1)=P(X=0,Y=1)/P(Y=1)=0.375, P(X=1/Y=1)=P(X=1,Y=1)/P(Y=1)=0.625I (X ;Y=1)=∑∑=====xx)P()1Y /(P log)1Y /(P )1Y (I )1Y /(P x x x x;x=1)P(X )1Y /1X (P log)1Y /1X (P 0)P(X )1Y /0X (P log)1Y /0X (P =====+===== =0.375log(0.375/0.75)+0.625log(0.625/0.25)=(5/8)log5-1≈0.45bit (b) 由于P(Z=1/ Y=1)=1, 所以 P (Y=1,Z=1/X=1)= P (Y=1/X=1)=0.5 P (Y=1,Z=1/X=0)= P (Y=1/X=0)=0.1那么P (Z=1/X=1)= P (Z=1,Y=1/X=1)+ P (Z=1,Y=0/X=1)=0.5+ P (Z=1/Y=0,X=1)P (Y=0/X=1)=0.5+0.5*0.4=0.7P(Z=1/X=0)= P (Z=1,Y=1/X=0)+ P (Z=1,Y=0/X=0)=0.1+P(Z=1/Y=0,X=0)P(Y=0/X=0)=0.1+0.9*0.4=0.46P (Z=1,X=1)= P (Z=1/X=1)*P(X=1)=0.7*0.25=0.175P (Z=1,X=0)= P (Z=1/X=0)*P(X=0)= 0.46*0.75=0.345 P(Z=1) = P(Z=1,X=1)+ P(Z=1,X=0) = 0.52 P(X=0/Z=1)=0.345/0.52=69/104 P(X=1/Z=1)=35/104I (X ;Z=1)=∑∑=====x x )P()1Z /(P log )1Z /(P )1Z (I )1Z /(P x x x x;x=1)P(X )1Z /1X (P log )1Z /1X (P 0)P(X )1Z /0X (P log )1Z /0X (P =====+======(69/104)log(23/26)+( 35/104)log(35/26) ≈0.027bit(c)H (X )=0.25*log(1/0.25)+0.75*log(1/0.75)=2-(3/4)log3=0.811bit H(Y/X)=-P(X=1,Y=1)logP(Y=1/X=1) -P(X=1,Y=0)logP(Y=0/X=1)-P(X=0,Y=1)logP(Y=1/X=0) -P(X=0,Y=0)logP(Y=0/X=0)=-0.125*log0.5-0.125*log0.5-0.075*log0.1-0.675*log0.9=1/4+(3/40)log10-(27/40)log(9/10)≈0.603bitH(XY)=H(X)+H(Y/X)=9/4+(3/4)log10-(21/10)log3=1.414bitP(X=0,Y=0,Z=0)= P(Z=0 / X=0, Y=0)* P( X=0, Y=0)=(1-0.4)*(0.75-0.075)=0.405 P(X=0,Y=0,Z=1)= P(Z=1 / X=0, Y=0)* P( X=0, Y=0)=0.4*0.675=0.27 P(X=1,Y=0,Z=1)= P(Z=1/ X=1,Y=0)* P(X=1,Y=0)=0.4*(0.25-0.125)=0.05 P(X=1,Y=0,Z=0)= P(Z=0/ X=1,Y=0)* P(X=1,Y=0)=0.6*0.125=0.075 P(X=1,Y=1,Z=1)=P(X=1,Z=1)- P(X=1,Y=0,Z=1)=0.175-0.05=0.125 P(X=1,Y=1,Z=0)=0 P(X=0,Y=1,Z=0)=0P(X=0,Y=1,Z=1)= P(X=0,Z=1)- P(X=0,Y=0,Z=1)= 0.345-0.27=0.075H(XYZ)=-0.405*log0.405-0.27*log0.27-0.05*log0.05-0.075*log0.075-0.125*log0.125-0.07 5*log0.075=(113/100)+(31/20)log10-(129/50)log3=0.528+0.51+0.216+0.28+0.375+0.28=2.189 bitH(Z/XY)=H(XYZ)-H(XY)= -28/25+(4/5)log10-12/25log3 =0.775bit2.9 解:A,B,C分别表示三个筛子掷的点数。
信息论英文课后部分习题答案
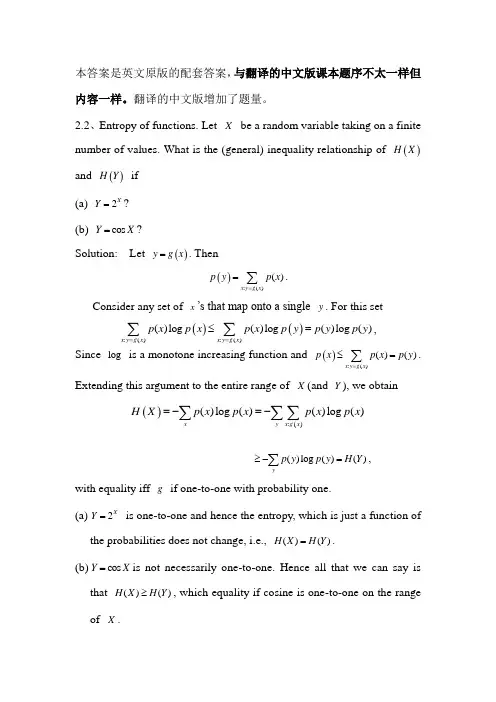
本答案是英文原版的配套答案,与翻译的中文版课本题序不太一样但内容一样。
翻译的中文版增加了题量。
2.2、Entropy of functions. Let X be a random variable taking on a finite number of values. What is the (general) inequality relationship of ()H X and ()H Y if(a) 2X Y =?(b) cos Y X =?Solution: Let ()y g x =. Then():()()x y g x p y p x ==∑.Consider any set of x ’s that map onto a single y . For this set()():():()()log ()log ()log ()x y g x x y g x p x p x p x p y p y p y ==≤=∑∑,Since log is a monotone increasing function and ():()()()x y g x p x p x p y =≤=∑.Extending this argument to the entire range of X (and Y ), we obtain():()()log ()()log ()x y x g x H X p x p x p x p x =-=-∑∑∑()log ()()yp y p y H Y ≥-=∑,with equality iff g if one-to-one with probability one.(a) 2X Y = is one-to-one and hence the entropy, which is just a function of the probabilities does not change, i.e., ()()H X H Y =.(b) cos Y X =is not necessarily one-to-one. Hence all that we can say is that ()()H X H Y ≥, which equality if cosine is one-to-one on the range of X .2.16. Example of joint entropy. Let (,)p x y be given byFind(a) ()H X ,()H Y .(b) (|)H X Y ,(|)H Y X . (c) (,)H X Y(d) ()(|)H Y H Y X -.(e) (;)I X Y(f) Draw a Venn diagram for the quantities in (a) through (e).Solution:Fig. 1 Venn diagram(a) 231()log log30.918 bits=()323H X H Y =+=.(b) 12(|)(|0)(|1)0.667 bits (/)33H X Y H X Y H X Y H Y X ==+===((,)(|)()p x y p x y p y =)((|)(,)()H X Y H X Y H Y =-)(c) 1(,)3log3 1.585 bits 3H X Y =⨯=(d) ()(|)0.251 bits H Y H Y X -=(e)(;)()(|)0.251 bits=-=I X Y H Y H Y X(f)See Figure 1.2.29 Inequalities. Let X,Y and Z be joint random variables. Prove the following inequalities and find conditions for equality.(a) )ZHYXH≥X(Z()|,|(b) )ZIYXI≥X((Z);,;(c) )XYXHZ≤Z-H-XYH),(,)(((X,,)H(d) )XYIZIZII+-XZY≥Y(););(|;;(Z|)(XSolution:(a)Using the chain rule for conditional entropy,HZYXHZXH+XH≥XYZ=),(|(Z)(||,()|)With equality iff 0YH,that is, when Y is a function of X andXZ,|(=)Z.(b)Using the chain rule for mutual information,ZIXXIZYX+=,I≥IYZ(|;)X);)(,;;(Z)(With equality iff 0ZYI, that is, when Y and Z areX)|;(=conditionally independent given X.(c)Using first the chain rule for entropy and then definition of conditionalmutual information,XZHYHIXZYX==-H-XHYYZ)()(;Z)|,|),|(X(,,)(XHXZH-Z≤,=,)()()(X|HWith equality iff 0ZYI, that is, when Y and Z areX(=|;)conditionally independent given X .(d) Using the chain rule for mutual information,);()|;();,();()|;(Z X I X Y Z I Z Y X I Y Z I Y Z X I +==+And therefore this inequality is actually an equality in all cases.4.5 Entropy rates of Markov chains.(a) Find the entropy rate of the two-state Markov chain with transition matrix⎥⎦⎤⎢⎣⎡--=1010010111p p p p P (b) What values of 01p ,10p maximize the rate of part (a)?(c) Find the entropy rate of the two-state Markov chain with transition matrix⎥⎦⎤⎢⎣⎡-=0 1 1p p P(d) Find the maximum value of the entropy rate of the Markov chain of part (c). We expect that the maximizing value of p should be less than 2/1, since the 0 state permits more information to be generated than the 1 state.Solution:(a) T he stationary distribution is easily calculated.10010*********,p p p p p p +=+=ππ Therefore the entropy rate is10011001011010101012)()()()()|(p p p H p p H p p H p H X X H ++=+=ππ(b) T he entropy rate is at most 1 bit because the process has only two states. This rate can be achieved if( and only if) 2/11001==p p , in which case the process is actually i.i.d. with2/1)1Pr()0Pr(====i i X X .(c) A s a special case of the general two-state Markov chain, the entropy rate is1)()1()()|(1012+=+=p p H H p H X X H ππ.(d) B y straightforward calculus, we find that the maximum value of)(χH of part (c) occurs for 382.02/)53(=-=p . The maximum value isbits 694.0)215()1()(=-=-=H p H p H (wrong!)5.4 Huffman coding. Consider the random variable⎪⎪⎭⎫ ⎝⎛=0.02 0.03 0.04 0.04 0.12 0.26 49.0 7654321x x x x x x x X (a) Find a binary Huffman code for X .(b) Find the expected codelength for this encoding.(c) Find a ternary Huffman code for X .Solution:(a) The Huffman tree for this distribution is(b)The expected length of the codewords for the binary Huffman code is 2.02 bits.( ∑⨯=)()(i p l X E )(c) The ternary Huffman tree is5.9 Optimal code lengths that require one bit above entropy. The source coding theorem shows that the optimal code for a random variable X has an expected length less than 1)(+X H . Given an example of a random variable for which the expected length of the optimal code is close to 1)(+X H , i.e., for any 0>ε, construct a distribution for which the optimal code has ε-+>1)(X H L .Solution: there is a trivial example that requires almost 1 bit above its entropy. Let X be a binary random variable with probability of 1=X close to 1. Then entropy of X is close to 0, but the length of its optimal code is 1 bit, which is almost 1 bit above its entropy.5.25 Shannon code. Consider the following method for generating a code for a random variable X which takes on m values {}m ,,2,1 with probabilities m p p p ,,21. Assume that the probabilities are ordered so thatm p p p ≥≥≥ 21. Define ∑-==11i k i i p F , the sum of the probabilities of allsymbols less than i . Then the codeword for i is the number ]1,0[∈i Frounded off to i l bits, where ⎥⎥⎤⎢⎢⎡=i i p l 1log . (a) Show that the code constructed by this process is prefix-free and the average length satisfies 1)()(+<≤X H L X H .(b) Construct the code for the probability distribution (0.5, 0.25, 0.125, 0.125).Solution:(a) Since ⎥⎥⎤⎢⎢⎡=i i p l 1log , we have 11log 1log +<≤i i i p l pWhich implies that 1)()(+<=≤∑X H l p L X H i i .By the choice of i l , we have )1(22---<≤ii l i l p . Thus j F , i j > differs from j F by at least il -2, and will therefore differ from i F is at least one place in the first i l bits of the binary expansion of i F . Thus thecodeword for j F , i j >, which has length i j l l ≥, differs from thecodeword for i F at least once in the first i l places. Thus no codewordis a prefix of any other codeword.(b) We build the following table3.5 AEP. Let ,,21X X be independent identically distributed random variables drawn according to theprobability mass function {}m x x p ,2,1),(∈. Thus ∏==n i i n x p x x x p 121)(),,,( . We know that)(),,,(log 121X H X X X p n n →- in probability. Let ∏==n i i n x q x x x q 121)(),,,( , where q is another probability mass function on {}m ,2,1.(a) Evaluate ),,,(log 1lim 21n X X X q n-, where ,,21X X are i.i.d. ~ )(x p . Solution: Since the n X X X ,,,21 are i.i.d., so are )(1X q ,)(2X q ,…,)(n X q ,and hence we can apply the strong law of large numbers to obtain∑-=-)(log 1lim ),,,(log 1lim 21i n X q n X X X q n 1..))((log p w X q E -=∑-=)(log )(x q x p∑∑-=)(log )()()(log )(x p x p x q x p x p )()||(p H q p D +=8.1 Preprocessing the output. One is given a communication channel withtransition probabilities )|(x y p and channel capacity );(max )(Y X I C x p =.A helpful statistician preprocesses the output by forming )(_Y g Y =. He claims that this will strictly improve the capacity.(a) Show that he is wrong.(b) Under what condition does he not strictly decrease the capacity? Solution:(a) The statistician calculates )(_Y g Y =. Since _Y Y X →→ forms a Markov chain, we can apply the data processing inequality. Hence for every distribution on x ,);();(_Y X I Y X I ≥. Let )(_x p be the distribution on x that maximizes );(_Y X I . Then__)()()(_)()()();(max );();();(max __C Y X I Y X I Y X I Y X I C x p x p x p x p x p x p ==≥≥===.Thus, the statistician is wrong and processing the output does not increase capacity.(b) We have equality in the above sequence of inequalities only if we have equality in data processing inequality, i.e., for the distribution that maximizes );(_Y X I , we have Y Y X →→_forming a Markov chain.8.3 An addition noise channel. Find the channel capacity of the following discrete memoryless channel:Where {}{}21Pr 0Pr ====a Z Z . The alphabet for x is {}1,0=X . Assume that Z is independent of X . Observe that the channel capacity depends on the value of a . Solution: A sum channel.Z X Y += {}1,0∈X , {}a Z ,0∈We have to distinguish various cases depending on the values of a .0=a In this case, X Y =,and 1);(max =Y X I . Hence the capacity is 1 bitper transmission.1,0≠≠a In this case, Y has four possible values a a +1,,1,0. KnowingY ,we know the X which was sent, and hence 0)|(=Y X H . Hence thecapacity is also 1 bit per transmission.1=a In this case Y has three possible output values, 0,1,2, the channel isidentical to the binary erasure channel, with 21=f . The capacity of this channel is 211=-f bit per transmission.1-=a This is similar to the case when 1=a and the capacity is also 1/2 bit per transmission.8.5 Channel capacity. Consider the discrete memoryless channel)11 (mod Z X Y +=, where ⎪⎪⎭⎫ ⎝⎛=1/3 1/3, 1/3,3 2,,1Z and {}10,,1,0 ∈X . Assume thatZ is independent of X .(a) Find the capacity.(b) What is the maximizing )(*x p ?Solution: The capacity of the channel is );(max )(Y X I C x p =)()()|()()|()();(Z H Y H X Z H Y H X Y H Y H Y X I -=-=-=bits 311log)(log );(=-≤Z H y Y X I , which is obtained when Y has an uniform distribution, which occurs when X has an uniform distribution.(a)The capacity of the channel is bits 311log /transmission.(b) The capacity is achieved by an uniform distribution on the inputs.10,,1,0for 111)( ===i i X p 8.12 Time-varying channels. Consider a time-varying discrete memoryless channel. Let n Y Y Y ,,21 be conditionally independent givenn X X X ,,21 , with conditional distribution given by ∏==ni i i i x y p x y p 1)|()|(.Let ),,(21n X X X X =, ),,(21n Y Y Y Y =. Find );(max )(Y X I x p . Solution:∑∑∑∑∑=====--≤-≤-=-=-=-=ni i n i i i n i i ni i i ni i i n p h X Y H Y H X Y H Y H X Y Y Y H Y H X Y Y Y H Y H X Y H Y H Y X I 111111121))(1()|()()|()(),,|()()|,,()()|()();(With equlity ifnX X X ,,21 is chosen i.i.d. Hence∑=-=ni i x p p h Y X I 1)())(1();(max .10.2 A channel with two independent looks at Y . Let 1Y and 2Y be conditionally independent and conditionally identically distributed givenX .(a) Show );();(2),;(21121Y Y I Y X I Y Y X I -=. (b) Conclude that the capacity of the channelX(Y1,Y2)is less than twice the capacity of the channelXY1Solution:(a) )|,(),(),;(212121X Y Y H Y Y H Y Y X I -=)|()|();()()(212121X Y H X Y H Y Y I Y H Y H ---+=);();(2);();();(2112121Y Y I Y X I Y Y I Y X I Y X I -=-+=(b) The capacity of the single look channel 1Y X → is );(max 1)(1Y X I C x p =.Thecapacityof the channel ),(21Y Y X →is11)(211)(21)(22);(2max );();(2max ),;(max C Y X I Y Y I Y X I Y Y X I C x p x p x p =≤-==10.3 The two-look Gaussian channel. Consider the ordinary Shannon Gaussian channel with two correlated looks at X , i.e., ),(21Y Y Y =, where2211Z X Y Z X Y +=+= with a power constraint P on X , and ),0(~),(221K N Z Z ,where⎥⎦⎤⎢⎣⎡=N N N N K ρρ. Find the capacity C for (a) 1=ρ (b) 0=ρ (c) 1-=ρSolution:It is clear that the two input distribution that maximizes the capacity is),0(~P N X . Evaluating the mutual information for this distribution,),(),()|,(),()|,(),(),;(max 212121212121212Z Z h Y Y h X Z Z h Y Y h X Y Y h Y Y h Y Y X I C -=-=-==Nowsince⎪⎪⎭⎫⎝⎛⎥⎦⎤⎢⎣⎡N N N N N Z Z ,0~),(21ρρ,wehave)1()2log(21)2log(21),(222221ρππ-==N e Kz e Z Z h.Since11Z X Y +=, and22Z X Y +=, wehave ⎪⎪⎭⎫⎝⎛⎥⎦⎤⎢⎣⎡++++N N P N N P N Y Y P P ,0~),(21ρρ, And ))1(2)1(()2log(21)2log(21),(222221ρρππ-+-==PN N e K e Y Y h Y .Hence⎪⎪⎭⎫⎝⎛++=-=)1(21log 21),(),(21212ρN P Z Z h Y Y h C(a) 1=ρ.In this case, ⎪⎭⎫⎝⎛+=N P C 1log 21, which is the capacity of a single look channel.(b) 0=ρ. In this case, ⎪⎭⎫⎝⎛+=N P C 21log 21, which corresponds to using twice the power in a single look. The capacity is the same as the capacity of the channel )(21Y Y X +→.(c) 1-=ρ. In this case, ∞=C , which is not surprising since if we add1Y and 2Y , we can recover X exactly.10.4 Parallel channels and waterfilling. Consider a pair of parallel Gaussianchannels,i.e.,⎪⎪⎭⎫⎝⎛+⎪⎪⎭⎫ ⎝⎛=⎪⎪⎭⎫ ⎝⎛212121Z Z X X Y Y , where⎪⎪⎭⎫ ⎝⎛⎥⎥⎦⎤⎢⎢⎣⎡⎪⎪⎭⎫ ⎝⎛222121 00 ,0~σσN Z Z , And there is a power constraint P X X E 2)(2221≤+. Assume that 2221σσ>. At what power does the channel stop behaving like a single channel with noise variance 22σ, and begin behaving like a pair of channels? Solution: We will put all the signal power into the channel with less noise until the total power of noise+signal in that channel equals the noise power in the other channel. After that, we will split anyadditional power evenly between the two channels. Thus the combined channel begins to behave like a pair of parallel channels when the signal power is equal to the difference of the two noise powers, i.e., when 22212σσ-=P .。
信息论考题及答案
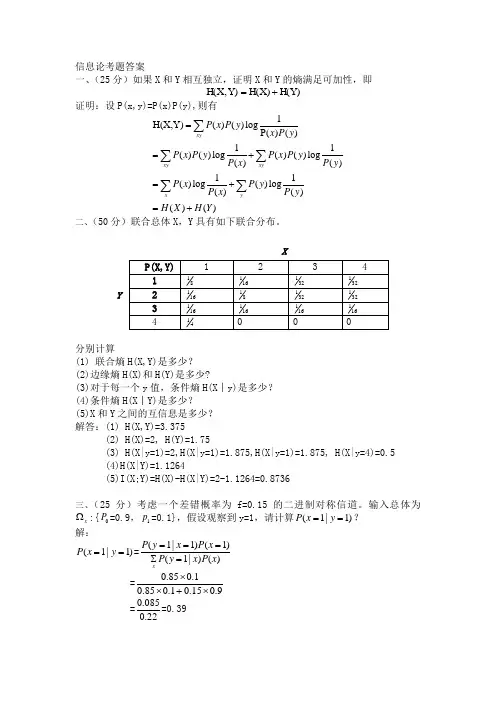
一、(25分)如果X 和Y 相互独立,证明X 和Y 的熵满足可加性,即 H(Y)H(X)Y)H(X,+= 证明:设P(x,y)=P(x)P(y),则有1H(X,Y)()()logP()()11()()log()()log ()()11()log()log ()()()()xyxyxy xy P x P y x P y P x P y P x P y P x P y P x P y P x P y H X H Y ==+=+=+∑∑∑∑∑二、(50分)联合总体X ,Y 具有如下联合分布。
XY分别计算(1) 联合熵H(X,Y)是多少? (2)边缘熵H(X)和H(Y)是多少?(3)对于每一个y 值,条件熵H(X ︱y)是多少? (4)条件熵H(X ︱Y)是多少? (5)X 和Y 之间的互信息是多少? 解答:(1) H(X,Y)=3.375(2) H(X)=2, H(Y)=1.75(3) H(X|y=1)=2,H(X|y=1)=1.875,H(X|y=1)=1.875, H(X|y=4)=0.5(4)H(X|Y)=1.1264(5)I(X;Y)=H(X)-H(X|Y)=2-1.1264=0.8736 三、(25分)考虑一个差错概率为f=0.15的二进制对称信道。
输入总体为x Ω:{0P =0.9,1p =0.1},假设观察到y=1,请计算(1|1)P x y ==? 解:(1|1)P x y ===(1|1)(1)(1|)()xP y x P x P y x P x ===∑==9.015.01.085.01.085.0⨯+⨯⨯=22.0085.0=0.39一、(25分)如果X 和Y 相互独立,证明X 和Y 的熵满足可加性,即 H(Y)H(X)Y)H(X,+=二、(50分)联合总体X ,Y 具有如下联合分布。
XY分别计算(1) 联合熵H(X,Y)是多少? (2)边缘熵H(X)和H(Y)是多少?(3)对于每一个y 值,条件熵H(X ︱y)是多少? (4)条件熵H(X ︱Y)是多少? (5)X 和Y 之间的互信息是多少?三、(25分)考虑一个差错概率为f=0.15的二进制对称信道。
信息论与编码(陈运)习题答案
· 1 ·2.1 试问四进制、八进制脉冲所含信息量是二进制脉冲的多少倍?解:四进制脉冲可以表示4个不同的消息,例如:{0, 1, 2, 3}八进制脉冲可以表示8个不同的消息,例如:{0, 1, 2, 3, 4, 5, 6, 7} 二进制脉冲可以表示2个不同的消息,例如:{0, 1} 假设每个消息的发出都是等概率的,则:四进制脉冲的平均信息量symbol bit n X H / 24log log )(1=== 八进制脉冲的平均信息量symbol bit n X H / 38log log )(2=== 二进制脉冲的平均信息量symbol bit n X H / 12log log )(0=== 所以:四进制、八进制脉冲所含信息量分别是二进制脉冲信息量的2倍和3倍。
2.2 居住某地区的女孩子有25%是大学生,在女大学生中有75%是身高160厘米以上的,而女孩子中身高160厘米以上的占总数的一半。
假如我们得知“身高160厘米以上的某女孩是大学生”的消息,问获得多少信息量?解:设随机变量X 代表女孩子学历X x 1(是大学生) x 2(不是大学生) P(X) 0.25 0.75设随机变量Y 代表女孩子身高Y y 1(身高>160cm ) y 2(身高<160cm ) P(Y) 0.5 0.5已知:在女大学生中有75%是身高160厘米以上的 即:bit x y p 75.0)/(11=求:身高160厘米以上的某女孩是大学生的信息量 即:bit y p x y p x p y x p y x I 415.15.075.025.0log )()/()(log )/(log )/(11111111=⨯-=-=-=2.3 一副充分洗乱了的牌(含52张牌),试问(1) 任一特定排列所给出的信息量是多少?(2) 若从中抽取13张牌,所给出的点数都不相同能得到多少信息量?解:(1) 52张牌共有52!种排列方式,假设每种排列方式出现是等概率的则所给出的信息量是:!521)(=i x p bit x p x I i i 581.225!52log )(log )(==-=(2) 52张牌共有4种花色、13种点数,抽取13张点数不同的牌的概率如下:· 2 ·bit C x p x I C x p i i i 208.134log)(log )(4)(135213135213=-=-==2.4 设离散无记忆信源⎭⎬⎫⎩⎨⎧=====⎥⎦⎤⎢⎣⎡8/14/1324/18/310)(4321x x x x X P X ,其发出的信息为(202120130213001203210110321010021032011223210),求 (1) 此消息的自信息量是多少?(2) 此消息中平均每符号携带的信息量是多少?解:(1) 此消息总共有14个0、13个1、12个2、6个3,因此此消息发出的概率是:62514814183⎪⎭⎫ ⎝⎛⨯⎪⎭⎫ ⎝⎛⨯⎪⎭⎫ ⎝⎛=p此消息的信息量是:bit p I 811.87log =-=(2) 此消息中平均每符号携带的信息量是:bit n I 951.145/811.87/==2.5 从大量统计资料知道,男性中红绿色盲的发病率为7%,女性发病率为0.5%,如果你问一位男士:“你是否是色盲?”他的回答可能是“是”,可能是“否”,问这两个回答中各含多少信息量,平均每个回答中含有多少信息量?如果问一位女士,则答案中含有的平均自信息量是多少?解: 男士:symbolbit x p x p X H bitx p x I x p bit x p x I x p i i i N N N Y Y Y / 366.0)93.0log 93.007.0log 07.0()(log )()( 105.093.0log )(log )(%93)( 837.307.0log )(log )(%7)(2=+-=-==-=-===-=-==∑女士:symbol bit x p x p X H ii i / 045.0)995.0log 995.0005.0log 005.0()(log )()(2=+-=-=∑2.6 设信源⎭⎬⎫⎩⎨⎧=⎥⎦⎤⎢⎣⎡17.016.017.018.019.02.0)(654321x x x x x x X P X ,求这个信源的熵,并解释为什么H(X) > log6不满足信源熵的极值性。
信息论习题集(陈运)
信息论习题集一、名词解释(25道)1、“本体论”的信息(P2)2、“认识论”信息(P2)3、离散信源(P7)4、自信息量(P9)5、离散平稳无记忆信源(P39)6、马尔可夫信源(P46)7、信源冗余度 (P51) 8、连续信源 (P52) 9、信道容量 (P73)10、强对称信道 (P75-76) 11、对称信道 (P78)12、多符号离散信道(P83)13、连续信道 (P95) 14、平均失真度 (P105) 15、实验信道 (P107)16、率失真函数 (P107) 17、信息价值率 (P127) 18、游程序列 (P143)19、游程变换 (P143) 20、L-D 编码(P146)、 21、冗余变换 (P146)22、BSC 信道 (P171) 23、码的最小距离 (P174)24、线性分组码 (P175)25、循环码 (P188)二、填空(100道)1、 在认识论层次上研究信息的时候,必须同时考虑到 形式、含义和效用 三个方面的因素。
2、 1948年,美国数学家 香农 发表了题为“通信的数学理论”的长篇论文,从而创立了信息论。
3、 按照信息的性质,可以把信息分成 语法信息、语义信息和语用信息 。
4、 按照信息的地位,可以把信息分成 客观信息和主观信息 。
5、 人们研究信息论的目的是为了 高效、可靠、安全 地交换和利用各种各样的信息。
6、 信息的 可度量性 是建立信息论的基础。
7、 统计度量 是信息度量最常用的方法。
8、 熵 是香农信息论最基本最重要的概念。
9、 事物的不确定度是用时间统计发生 概率的对数 来描述的。
10、单符号离散信源一般用随机变量描述,而多符号离散信源一般用 随机矢量 描述。
11、一个随机事件发生某一结果后所带来的信息量称为自信息量,定义为 其发生概率对数的负值 。
12、自信息量的单位一般有 比特、奈特和哈特 。
13、必然事件的自信息是 0 。
14、不可能事件的自信息量是 ∞ 。
信息论与编码(第二版)习题答案,陈运,主编
信息论与编码(第二版)习题答案,陈运,主编篇一:信息论与编码复习资料重点陈运第二版 2.3 居住某地区的女孩子有25%是大学生,在女大学生中有75%是身高160厘米以上的,而女孩子中身高160厘米以上的占总数的一半。
假如我们得知“身高160厘米以上的某女孩是大学生”的消息,问获得多少信息量?解:设随机变量X代表女孩子学历 X P(X) x1(是大学生) 0.25 x2(不是大学生) 0.75 设随机变量Y代表女孩子身高 Y P(Y) y1(身高 160cm) 0.5 y2(身高 160cm) 0.5 已知:在女大学生中有75%是身高160厘米以上的即:p(y1/x1)?0.75 bit 求:身高160厘米以上的某女孩是大学生的信息量即:I(x1/y1)??logp(x1/y1)??log p(x1)p(y1/x1) p(y1) ??log 0.25?0.75 0.5 ?1.415 bit 2.4 设离散无记忆信源? ??x1?0??? ?P(X)??3/8? X x2?1x3?21/4 1/4 x4?3? ?,其发出的信息1/8? 为(202120130213001203210110321010021032011223210),求 (1) 此消息的自信息量是多少? (2) 此消息中平均每符号携带的信息量是多少?解: (1) 此消息总共有14个0、13个1、12个2、6个3,因此此消息发出的概率是: ?3?p??? ?8?14 ?1?????4? 25 ?1???? ?8? 6 此消息的信息量是:I??logp?87.811 bit (2) 此消息中平均每符号携带的信息量是:I/n?87.811/45?1.951 bit 2.5 从大量统计资料知道,男性中红绿色盲的发病率为7%,女性发病率为0.5%,如果你问一位男士:“你是否是色盲?”他的回答可能是“是”,可能是“否”,问这两个回答中各含多少信息量,平均每个回答中含有多少信息量?如果问一位女士,则中含有的平均自信息量是多少?解:男士:p(xY)?7% I(xY)??logp(xY)??log0.07?3.837 bitp(xN)?93% I(xN)??logp(xN)??log0.93?0.105 bit 2 H(X)???p(xi)logp(xi)??(0.07log0.07?0.93log0.93)?0.366 bit/symbol i 女士: 2 H(X)???p(xi)logp(xi)??(0.005log0.005?0.995log0.995)?0.045 bit/symbol i 2.7 同时掷出两个正常的骰子,也就是各面呈现的概率都为1/6,求:(1) “3和5同时出现”这事件的自信息;(2) “两个1同时出现”这事件的自信息; (3) 两个点数的各种组合(无序)对的熵和平均信息量; (4) 两个点数之和(即2, 3, ? , 12构成的子集)的熵; (5) 两个点数中至少有一个是1的自信息量。
信息论与编码试题集与答案(新)
1. 在无失真的信源中,信源输出由 H (X ) 来度量;在有失真的信源中,信源输出由 R (D ) 来度量。
2. 要使通信系统做到传输信息有效、可靠和保密,必须首先 信源 编码, 然后_____加密____编码,再______信道_____编码,最后送入信道。
3. 带限AWGN 波形信道在平均功率受限条件下信道容量的基本公式,也就是有名的香农公式是log(1)C W SNR =+;当归一化信道容量C/W 趋近于零时,也即信道完全丧失了通信能力,此时E b /N 0为 -1.6 dB ,我们将它称作香农限,是一切编码方式所能达到的理论极限。
4. 保密系统的密钥量越小,密钥熵H (K )就越 小 ,其密文中含有的关于明文的信息量I (M ;C )就越 大 。
5. 已知n =7的循环码42()1g x x x x =+++,则信息位长度k 为 3 ,校验多项式 h(x)= 31x x ++ 。
6. 设输入符号表为X ={0,1},输出符号表为Y ={0,1}。
输入信号的概率分布为p =(1/2,1/2),失真函数为d (0,0) = d (1,1) = 0,d (0,1) =2,d (1,0) = 1,则D min = 0 ,R (D min )= 1bit/symbol ,相应的编码器转移概率矩阵[p(y/x )]=1001⎡⎤⎢⎥⎣⎦;D max = 0.5 ,R (D max )= 0 ,相应的编码器转移概率矩阵[p(y/x )]=1010⎡⎤⎢⎥⎣⎦。
7. 已知用户A 的RSA 公开密钥(e,n )=(3,55),5,11p q ==,则()φn = 40 ,他的秘密密钥(d,n )=(27,55) 。
若用户B 向用户A 发送m =2的加密消息,则该加密后的消息为 8 。
二、判断题1. 可以用克劳夫特不等式作为唯一可译码存在的判据。
(√ )2. 线性码一定包含全零码。
(√ )3. 算术编码是一种无失真的分组信源编码,其基本思想是将一定精度数值作为序列的 编码,是以另外一种形式实现的最佳统计匹配编码。